The first independent tests of Nvidia’s RTX Spark, a processor the company has built for laptops, appeared on October 15, and they measured something the PC industry has not traditionally benchmarked: how often a machine can finish an agentic task without help. The results give buyers a measurable comparison in a category that both companies have so far described in generalities.
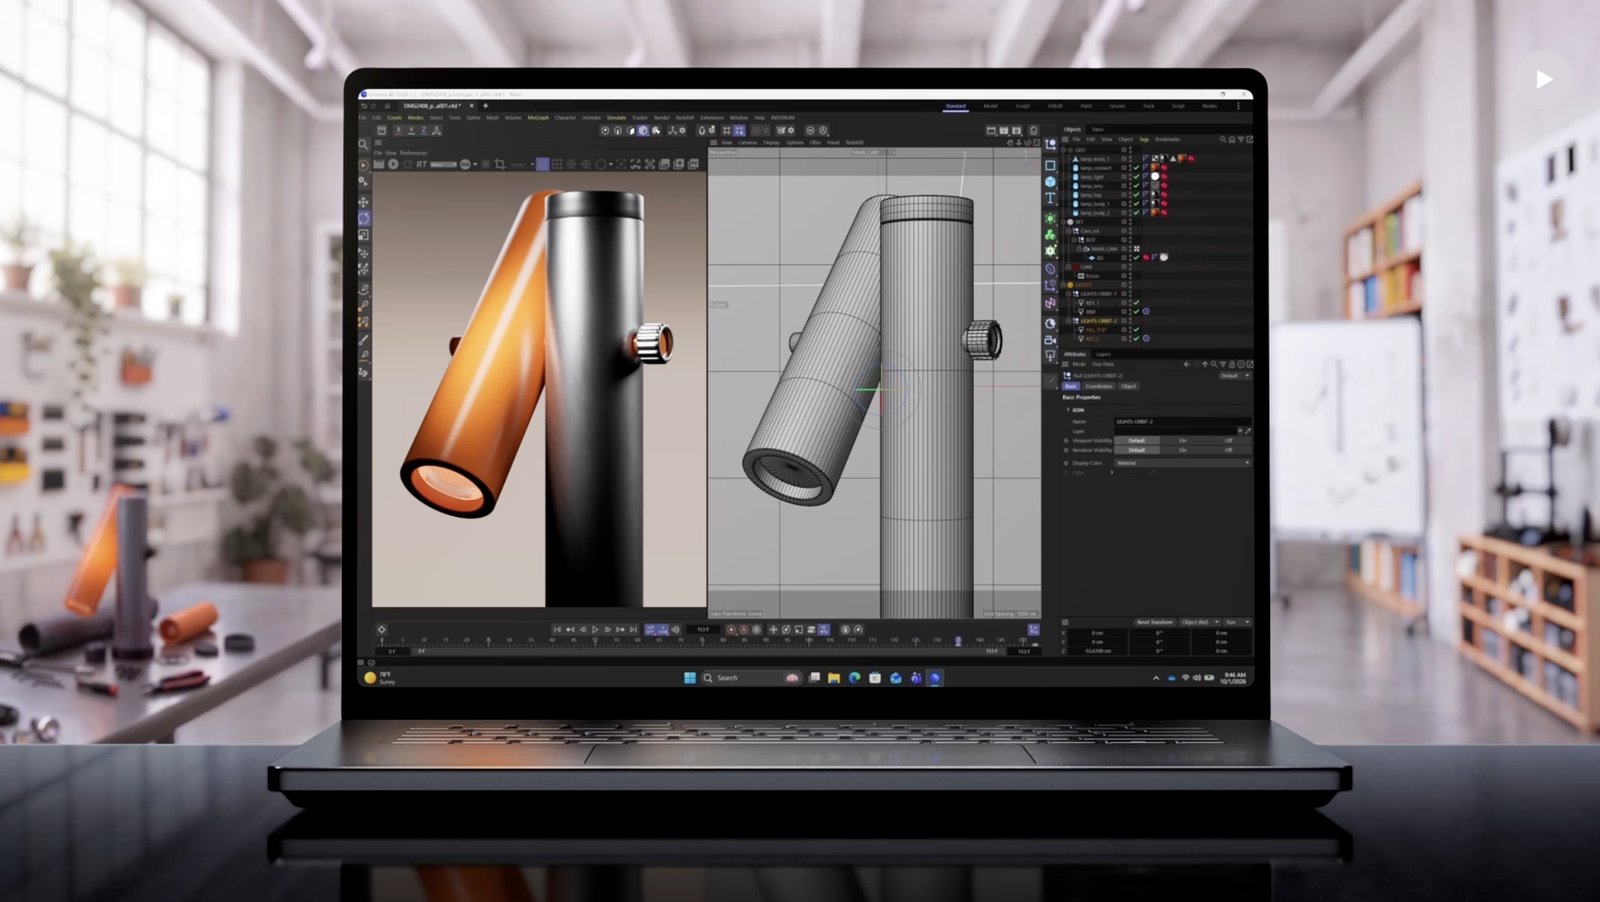
Tom’s Hardware tested the chip inside the Surface Laptop Ultra, running agentic workloads built on models from the Qwen family, and found a completion rate roughly 25 percent higher than a MacBook Pro equipped with Apple’s M5 Max. Both machines are meant to run models locally rather than sending every request to a server, which makes the result a test of memory, scheduling and power management as much as of raw arithmetic.
RTX Spark is built on Arm architecture, a deliberate departure from the x64 path that AMD and Intel have followed for decades, and it pairs a central processor with a separate graphics chip. Nvidia has positioned the combination for local AI and for gaming, two workloads that both depend on moving large amounts of data quickly and keeping a machine cool enough to sustain it.
Microsoft reworked parts of Windows to accompany the product line. The company adjusted how the operating system manages memory and how it schedules local models, and it said Windows 11 now runs more smoothly on machines with 8 gigabytes of memory. That claim is aimed at the segment of the market that buys inexpensive laptops, a group that has been largely left out of the on-device AI discussion because the models do not fit.
The first laptops using the chip were introduced in San Francisco last week. The Surface Laptop Ultra is the reference machine for the review cycle, and its results will shape how the rest of the industry reads the platform.
Analysts said the significance of the test lies less in the margin than in what it measures. Completion rate on an agentic task reflects whether a model can plan, call tools and recover from mistakes across many steps, and a machine that finishes 25 percent more of those runs is more useful than one that answers a single question slightly faster. Buyers who have been told that local AI is a feature rather than a capability now have a number to compare, even if it comes from one review of one configuration.
The comparison with Apple is the part likely to travel furthest. Apple has spent years arguing that its own silicon, paired with its own operating system, produces better results per watt than anything assembled from parts. Nvidia is making the opposite bet: that a specialized graphics processor and an Arm core, supported by a software layer Microsoft controls, can match or beat a competitor that designs everything itself.
The caveats are substantial. A single test on a single machine under one reviewer’s conditions is not a product verdict, and results can shift with model size, memory bandwidth, thermal limits and how the agent framework is written. Nvidia’s claim will need to hold across multiple vendors, several price points and the long-running workloads that battery-powered machines handle worst.
Memory supply puts a ceiling on how fast the category can grow. The components that let a laptop hold a model in place are the same ones the data center business is competing for, and prices have risen across the market. A chip designed to run models locally is only as useful as the memory attached to it, and that memory is currently the tighter constraint.
Arm licensing shapes what comes next. Because the architecture is licensed rather than owned, several chipmakers can design parts on the same foundation, which is how the platform spreads quickly once a reference product proves out. It also means Nvidia’s advantage has to come from the graphics core and from the software it ships, not from any exclusive access to the processor design.
Software compatibility decides whether buyers care. Windows on Arm has improved over several years, but applications compiled for x64 still run through translation layers in many cases, and translation costs power. A laptop that finishes more agent tasks but struggles with a customer’s primary application will not be chosen, and Microsoft’s reworking of memory management is aimed squarely at that gap.
What buyers will watch is the entry price. A chip that pairs a central processor with a discrete graphics unit costs more to build than an integrated design, and the machines that sell in the largest volumes are the ones whose price is lowest. Nvidia’s pitch to the consumer market has always rested on the top of the range, and the question is whether this line can be sold profitably at the bottom of it.
For Microsoft, the product line is a way to sell the idea that Windows is the platform where local AI runs best, which has become harder to argue as the most capable models remain tied to remote servers. For Nvidia, it opens a consumer category beyond graphics cards while the data center business absorbs nearly all of its production capacity. Neither company has said what the laptops will cost, how many models will run well on them at the entry-level memory configuration, or what happens to the comparison when the next generation of Apple silicon arrives. Those answers will decide whether this week’s number becomes a benchmark or an anecdote.