Nvidia’s product pages are the closest thing the industry has to a timetable. When a figure changes there, buyers plan around it, and competitors answer it. Sometime after June, several of the figures for Vera Rubin changed, and nobody at the company said so.
The edits were caught by comparing the current Vera Rubin NVL72 page against archived copies held by the Wayback Machine, a comparison first published by Guru3D and the Chinese outlet ITHome, then confirmed by others checking the same snapshots. Nvidia has not explained the revision or announced that one was made.
On the superchip, the package that pairs two Rubin GPUs with a Vera central processor, published HBM4 memory bandwidth fell to 38.5 terabytes a second from 44. NVLink, the link that lets GPUs read each other’s memory, fell to 6 terabytes a second from 7.2. Both cuts are between 12% and 17%. The scale-out network, the fabric that connects one rack to the next, went the other way, rising to 0.9 terabytes a second from 0.8.
The per-chip numbers moved with them. A single Rubin GPU now lists 19.2 terabytes a second of HBM4 bandwidth, down from 22, and 3 terabytes a second of bidirectional NVLink, down from 3.6. The pin rate behind the memory figure dropped to 9.3 gigabits a second from 11.7, which is the number that explains the rest: bandwidth is pin rate multiplied by bus width, and the width did not change.
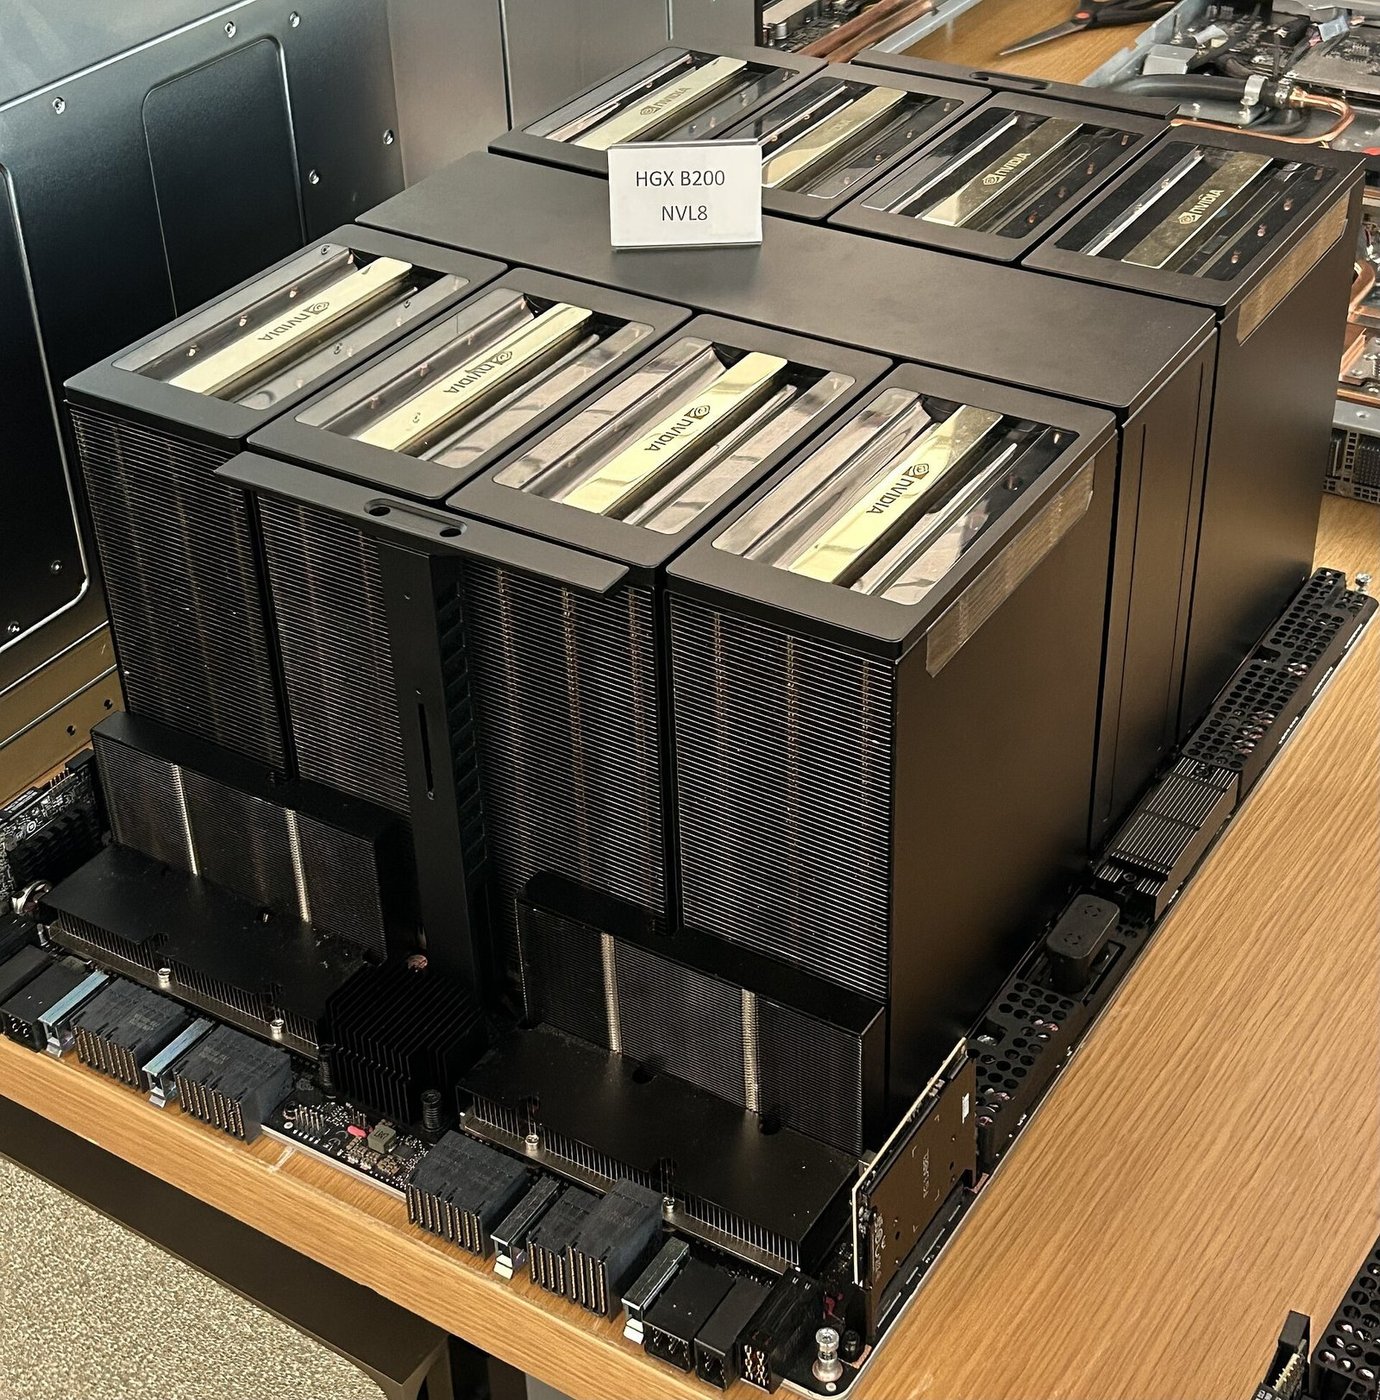
At rack scale the arithmetic compounds. The NVL72 configuration, 72 Rubin GPUs and 36 Vera processors in one cabinet, now lists 1,400 terabytes a second of aggregate HBM4 bandwidth against 1,580 before, and 216 terabytes a second of NVLink against 260. Memory capacity is untouched at 20.7 terabytes, so the system holds the same data and moves it more slowly. The smaller HGX Rubin NVL8 took the deepest cut: HBM4 bandwidth down 26% to 130 terabytes a second, capacity down to 2 terabytes from 2.3.
Not every line fell. Nvidia raised scale-out networking by about 12.5% across the board, and the four-GPU NVL4 configuration now lists 1 terabyte a second of scale-out bandwidth against 0.4 before. Advertised inference throughput, 50 petaflops of sparse NVFP4, is unchanged, as are the training figures for the largest rack.
Why the numbers moved is not public. Reporting based on SemiAnalysis research has said memory suppliers were struggling to hit the bandwidth Nvidia originally specified for HBM4, and that easing the target improves yields. That explanation fits the shape of the edits: memory and the on-package interconnect came down, the network between racks went up, and the marketing figure for compute stayed put.
The HBM4 context makes the pressure legible. The standard doubles the interface width to 2,048 bits per stack, which is how the first generation of parts reaches bandwidth that HBM3E could not. Wider buses are harder to build, and every stack that misses a speed bin is a stack a supplier cannot sell at the top price. Nvidia buys from three suppliers — SK Hynix, Samsung and Micron — and its published specification is also a purchasing target that three factories have to hit at once.
For customers the change is a planning problem, not a recall. Model training is sensitive to memory bandwidth in ways that are easy to measure and hard to argue with: attention kernels, mixture-of-experts routing and long-context inference all spend their time waiting on memory rather than arithmetic. A 12% cut on a bandwidth-bound workload is close to a 12% cut in throughput, while a compute-bound job might not notice. Nvidia’s own marketing mixes both, which is why the 50-petaflop figure survived an edit that touched everything feeding it.
The disclosure problem may outlast the specification. Nvidia’s pages are now inconsistent with each other: the HGX product page carries the revised system-level numbers while still listing 22 terabytes a second and 3.6 terabytes a second for the individual GPU, and some regional sites have not been updated at all. A buyer comparing two documents from the same vendor can reach two different conclusions about the same part.
The comparison with the current generation is the one buyers will make. Blackwell parts ship with HBM3E running at roughly 8 terabytes a second per GPU, and Rubin’s whole pitch was that HBM4 would widen that gap. A 19.2-terabyte figure still doubles the predecessor. It is simply less than the doubling Nvidia advertised in June, which changes the case for upgrading a rack that is already paid for.
Archived pages make quiet revisions permanent. Before the Wayback Machine, a specification could be softened and only the sales engineers would know. Now the June version sits in a public archive, and the delta is a data point that competitors, analysts and customers can all cite. The next time Nvidia publishes a number, the useful question will be which version of the page it came from.
None of this settles what the hardware does. These are platform specifications, not benchmarks, and the first systems have not reached customers in volume. What the documents show is a company adjusting a target it set when memory makers were more optimistic, and choosing not to say so. Buyers who sized clusters on the June figures are working from a plan that no longer matches the paperwork.